Projects
23 projects. Newest and featured first.
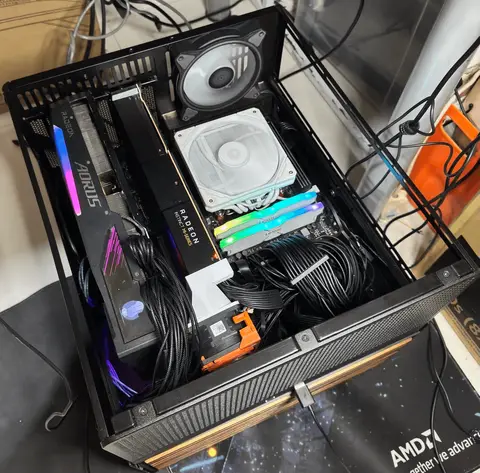
Proxmox AI Datacenter
Home lab running on Proxmox: LXC containers and VMs for LLM inference, monitoring, and general compute.
Chrome AI Privacy Extension
Chrome extension using the Prompt API and Gemini Nano for on-device text classification. Runs entirely in the browser with no server-side inference.
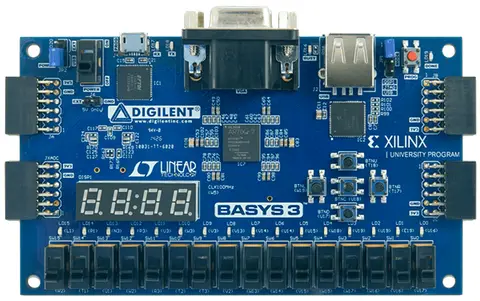
uP16 · 5-Stage RISC CPU
5-stage pipelined 16-bit RISC CPU written in Verilog and synthesized on an Artix-7 FPGA. Register file and program counter readable live on hardware via Vivado.
Portfolio Website
This site: a 3D room with a Windows XP desktop on the monitor, built with Astro and three.js, deployed to GitHub Pages.
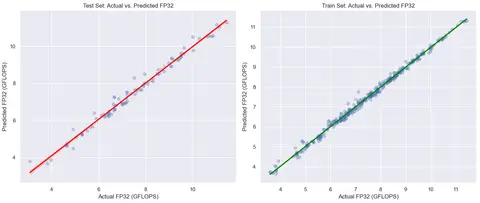
GPU Performance Prediction
Ensemble models predicting GPU FP32 performance from hardware specs. Scraped 497 AMD and Nvidia chips from TechPowerUp (2006 to 2024), compared Random Forest, XGBoost, and Gradient Boosting. XGBoost on log-transformed features achieved R² 0.984 on the test set.
Payhere · P2P Payments
P2P payment PWA built at SUTD What The Hack. Voice-activated payee selection using NLP, geospatial queries in DynamoDB, AWS Lambda and Stripe on the backend.
VLASH-Forge
Distributed fine-tuning framework for VLA robot policies built on HuggingFace LeRobot. Fine-tune π₀.₅ on custom tasks from 12 GB VRAM and deploy to a Jetson AGX Orin at 30 Hz with a single command.
DA3 Underwater: LoRA Depth Estimation for AUV
LoRA fine-tuning of Depth Anything 3 for underwater metric depth estimation, integrated into a ROS 2 AUV localisation pipeline. 59% AbsRel reduction, validated in live pool tests with the NTU Mecatron AUV team.
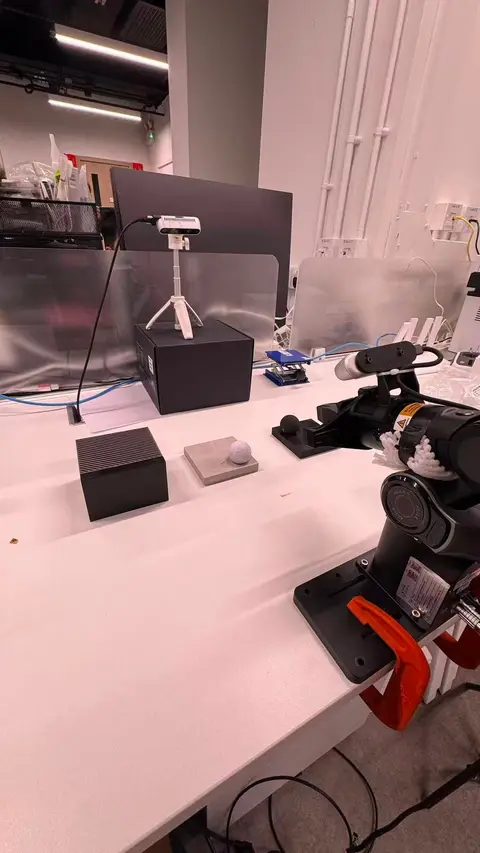
VLASH-Piper: VLA Edge Deployment on Jetson AGX Orin
First known deployment of π₀.₅ on a 6-DOF Piper arm running entirely on a Jetson AGX Orin. 29.5x latency reduction and 65% task success rate from 50 kinesthetic demonstrations, using VLASH async inference with no datacenter GPU at runtime.
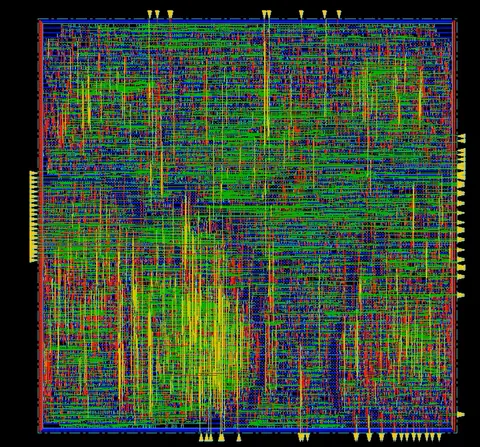
Mixed-Precision MAC Unit: TSMC 180nm ASIC
Fixed/floating-point merged MAC unit through full RTL-to-GDSII on TSMC 180nm. FP16×FP16→FP32 accumulation and dual INT8 multiplication on a shared datapath, 4.6% area overhead vs a standalone FP MAC, 157 MHz critical path.
Founding the NTU Semiconductor Club
Founded NTU's first dedicated semiconductor student club from scratch: faculty approval, industry partnerships, site visits, and lab access. Grew to 400 members.
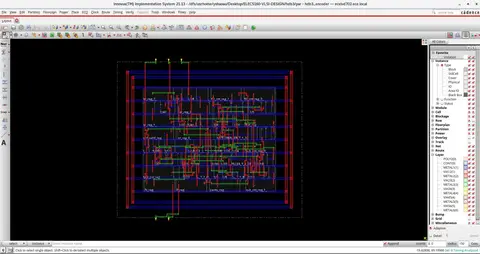
HDB3 Line Encoder: TSMC 180nm ASIC
HDB3 line encoder RTL-to-GDSII on TSMC 180nm. 4-bit lookahead shift register, 54 cells, 1,442 µm² cell area, timing closed at 250 MHz constraint with 0.961 ns post-PAR slack.
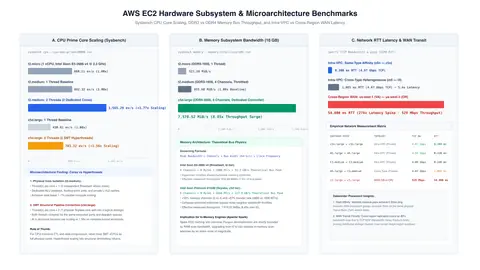
Distributed Big Data Engines: MapReduce Patterns, Spark Shuffling & Kubernetes Orchestration
Systems evaluation of distributed compute: MapReduce Order Inversion & Stripes, Spark shuffle memory mechanics, bare-metal Hadoop/EMR, and Kubernetes microservice orchestration.
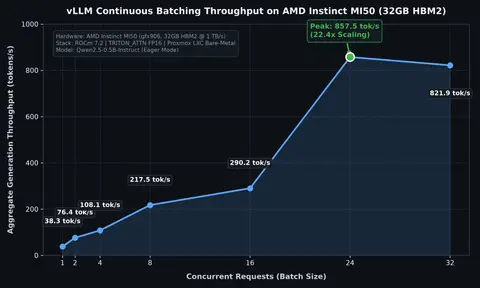
AMD Instinct MI50 vLLM Port & Container Passthrough
Porting continuous-batching vLLM to legacy GCN 5.1 (gfx906) datacenter silicon, configuring unprivileged Proxmox LXC KFD character device passthrough, and reaching 422 tok/s on 32GB HBM2.
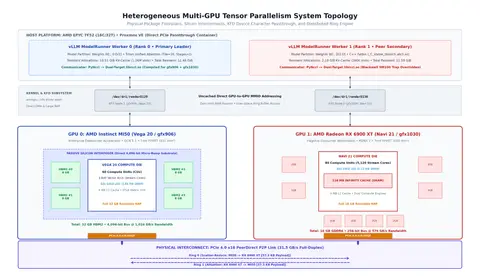
Heterogeneous AMD Tensor Parallelism Engine (MI50 + RX 6900 XT)
First working cross-generational AMD Tensor Parallelism engine bridging enterprise datacenter silicon (Instinct MI50, gfx906) and consumer desktop GPUs (Radeon RX 6900 XT, gfx1030) in vLLM via a custom dual-target librccl.so fatbin and PCIe 4.0 P2P DMA.
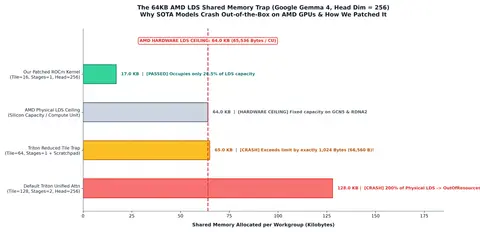
ROCm Microarchitecture & 64KB LDS Kernel Engineering
Diagnosing the 64KB Local Data Share (LDS) hardware barrier on large-head models (Gemma 4 d_head=256), authoring the tile=16 Triton attention clamp, and analyzing the 44% MoE straggler stall.
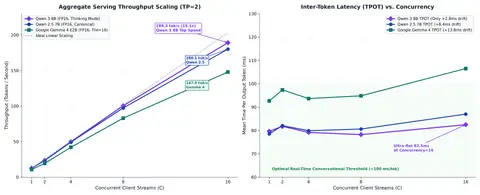
Distributed LLM Concurrency Suite & Systems Benchmarks
Empirical continuous-batching concurrency sweep (C=1 to 16) across Qwen 3 8B, Qwen 2.5 7B, and Gemma 4 in TP=2, measuring 189 tok/s peak throughput and +2.8ms latency drift.
Homelab Telemetry: Proxmox, InfluxDB & Grafana
Two LXCs and one host agent: Proxmox's external metric server and Telegraf push to InfluxDB 2.8, and a 33-panel Grafana 12.3 dashboard covers guests, EPYC package power, and both GPUs.
vLLM Formally Verified Sliding-Window Prefix Cache Optimization
Formally verified an O(N/W + W) stride jump search for sliding-window prefix caching in vLLM V1, replacing an O(N) backwards linear scan. Lean 4 proofs, up to 61.3x lower CPU scheduler stalls, upstream pull request #65086.
Autonomous Ackermann Robot Car: ROS 2 Distributed Stack, Gazebo Digital Twin and STM32 Velocity Control
Ackermann robot car running a distributed ROS 2 stack across a Raspberry Pi and a laptop, with a Gazebo digital twin, Foxglove telemetry and STM32 velocity control.
NSyM RTL: Training Multimodal Language Models for Neurosymbolic, Automated HDL Code Generation
Co-author of a preprint on training multimodal language models to write Verilog from K-maps, circuit diagrams and state diagrams. I built most of the testing harness.
Computer Vision Anomaly Detection for Semiconductor Defect Classification
Industry-sponsored final year project with AMD: a computer vision anomaly detection pipeline for semiconductor defect classification on wafer test images.
GDG Singapore Hermes Workshop: Self-Hosted AI Agents on Google Cloud
Designed and led a hands-on workshop on the Hermes agent framework for the Google Developer Group Singapore meetup on 23 Sep 2026. I wrote the curriculum, deck and presenter script, and coordinated a four-person speaker line-up.